User Persona Building: a Tokeny case study
Combine survey data and user behavior analysis to build detailed target user personas. Follow the recorded task, execution screenshots, actual files and verification notes.
By the Tokeny team · Windows · Tokeny 1.7.8 · gpt-6-sol
Prepare the inputs
Create a separate workspace in Tokeny, download and unpack the sample inputs, then select a model that supports tools. The sample uses synthetic data or the public sources named in the article.
- survey.csv
Send the task to Tokeny
The original task was executed in Chinese. Copying these instructions reproduces the same task; the results below include an English report.
使用匿名问卷构建两个工作型用户画像,区分数据观察与推测,给出人数依据和功能建议,不推测受访者的年龄收入。

交付文件:personas.md、segments.csv。
验收要点:
- 引用 12 人样本
- 每个人群有数据依据
- 推断被明确标记
这是使用合成演示输入或指定公开资料的真实操作案例。请先读取工作空间输入,再实际生成文件并自检。所有写入、脚本与临时服务限于当前工作空间;临时服务只监听 127.0.0.1,执行后关闭;不触达外部收件人、不发布、不付款、不更改系统设置,不调用子智能体。需要公开资料时可读取给定 URL。只启用完成任务必需的工具。另写 report.md(中文)和 report.en.md(英文),简洁、完整,包含输入、处理步骤、真实结果、检查方式和局限;失败或未验证部分如实记录,不能宣称成功。最终回复用中文列出产物、关键结果与待核实项。
排版检查:Word 主标题仅出现一次,标题为黑色且与后续正文或表格保持同页;Excel 表头和长文字不能被窄列截断,合理设置列宽、换行、行高;HTML 在 390px 视口不能整页横向溢出。报告没有固定字数要求,不要为字数反复改写。
The recorded run used an isolated demonstration workspace. Review the commands and file paths before approving operations in your own workspace.
What actually ran
The task was submitted through the Tokeny input box. An online model read the inputs and executed tools. This run covers the local sample task and its actual files. Results and checks are recorded below.
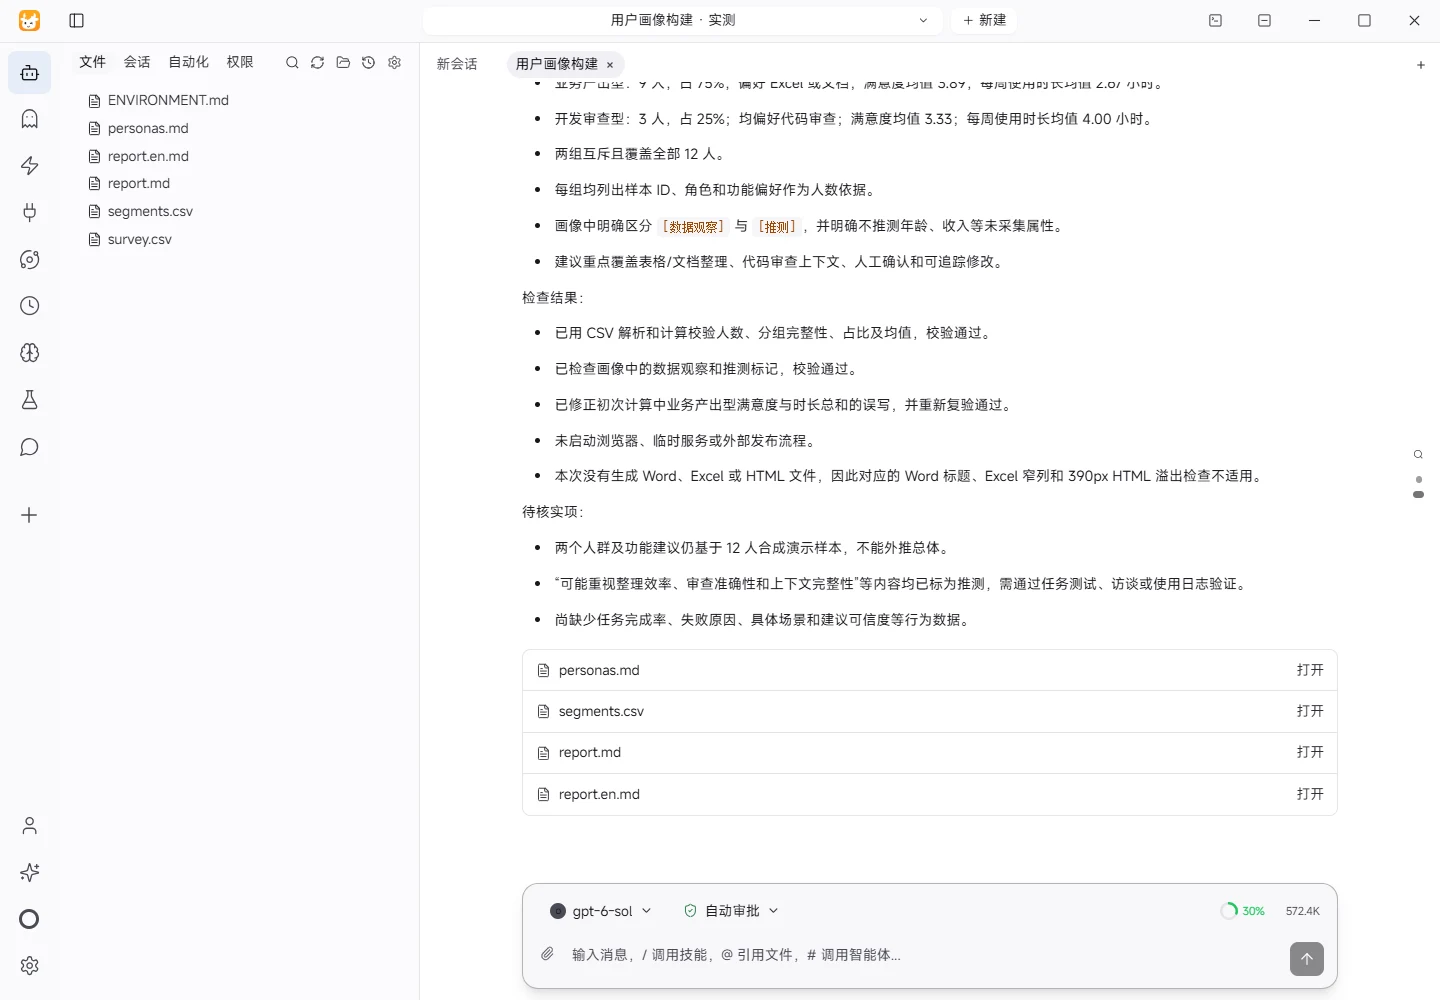
Results and verification
Input
I read survey.csv from the workspace. It contains 12 anonymous responses with the fields id, role, satisfaction, preferred_feature, and weekly_hours. I also read ENVIRONMENT.md to confirm the isolated demonstration environment and available local document/table tooling. The input has no age or income fields, so those attributes were not inferred.
Processing
- Checked the CSV header, record count, and observed values.
- Created two mutually exclusive segments from
preferred_feature:Excelor文档became “Business Output”;代码审查became “Development Review”. - Calculated count, share, mean satisfaction, and mean weekly hours for each segment, retaining sample IDs as the count evidence.
- Marked direct counts and calculations as “data observation” and unverified work hypotheses as “inference”.
- Generated
personas.md,segments.csv, and Chinese/English reports.
Actual Results
- Business Output: 9/12 people (75%), IDs 1, 2, 5, 6, 7, 8, 9, 10, and 12; mean satisfaction 3.89; mean weekly use 2.67 hours.
- Development Review: 3/12 people (25%), IDs 3, 4, and 11; mean satisfaction 3.33; mean weekly use 4.00 hours.
- The two segments cover all 12 responses. Suggestions focus on spreadsheet/document workflows and code-review context plus human confirmation. The persona document separates observations from inferences explicitly.
Checks
- Compared the segment IDs with
survey.csvand verified that all 12 IDs appear exactly once. - Rechecked the denominators and shares: 9 + 3 = 12 and 75% + 25% = 100%.
- Recalculated means: Business Output satisfaction 35/9 and weekly hours 24/9; Development Review satisfaction 10/3 and weekly hours 12/3.
- Checked that
personas.mdcites the 12-person sample, lists IDs for both segments, uses[数据观察]and[推测]labels, and states the age/income boundary. - Checked that
segments.csvcontains headers, sample IDs, evidence, inference, and feature-suggestion columns. This delivery is CSV, so spreadsheet column rendering and HTML viewport rendering do not apply.
Limitations
The sample has only 12 anonymous, cross-sectional, synthetic demonstration responses and is not a representative sample. Role and feature preference do not support population-level generalization. The questionnaire does not measure task outcomes, failure reasons, context, age, income, or other demographic attributes, so causal conclusions and demographic profiling are out of scope. No browser, temporary service, external publication, or supplementary public-source validation was used because none was needed for the supplied input.
Download and inspect the outputs
The archive contains the files created during this run. Use these checks when adapting the example to your own data.
- Reconcile the reported results against the downloadable sample inputs.
- Open the generated files and check the contents relevant to your task.
- Review the limitations and any unverified steps in the report.